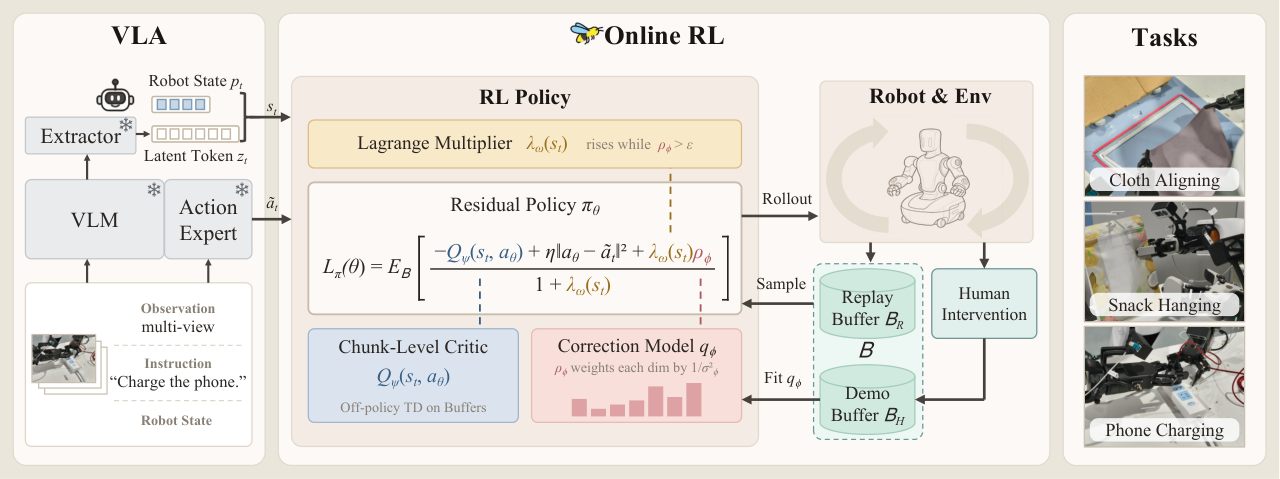
A residual policy on a frozen VLA. Human corrections set a per-dimension constraint, with tighter bounds where people agree and looser ones where they don't.
I build vision-language-action models for robot manipulation at AgiBot. The part I work on is post-training with reinforcement learning: residual policies that take human corrections, one policy that keeps earlier tasks while it learns new ones, and action-level evaluation on real robots.
Before AgiBot I was at NIO, and a research intern at AIR, Tsinghua University. My master's at Tongji, with Gang Wei, was 3D scene understanding: zero-shot instance segmentation, semantic Gaussian splatting, and a lightweight 3D-LLM. The thread through all of that is still multimodal models, 3D vision, and reinforcement learning.
* indicates equal contribution. † indicates corresponding author.
A residual policy on a frozen VLA. Human corrections set a per-dimension constraint, with tighter bounds where people agree and looser ones where they don't.
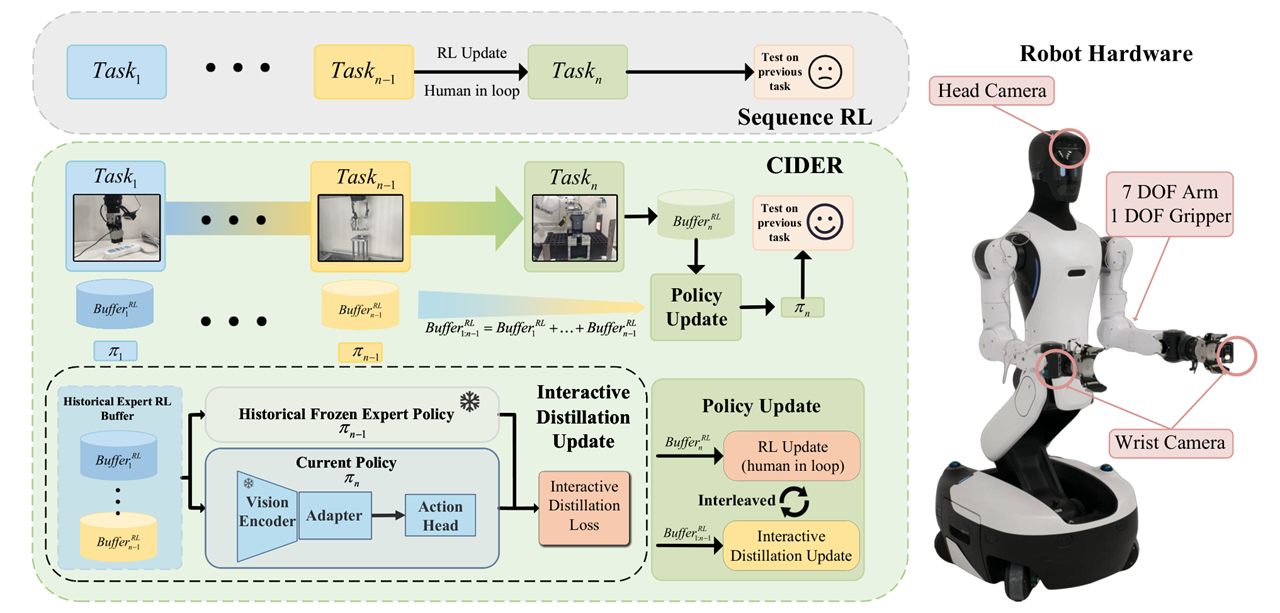
One policy learns six real-robot tasks in sequence. Each new task takes 10–20 minutes, and the earlier ones stay.
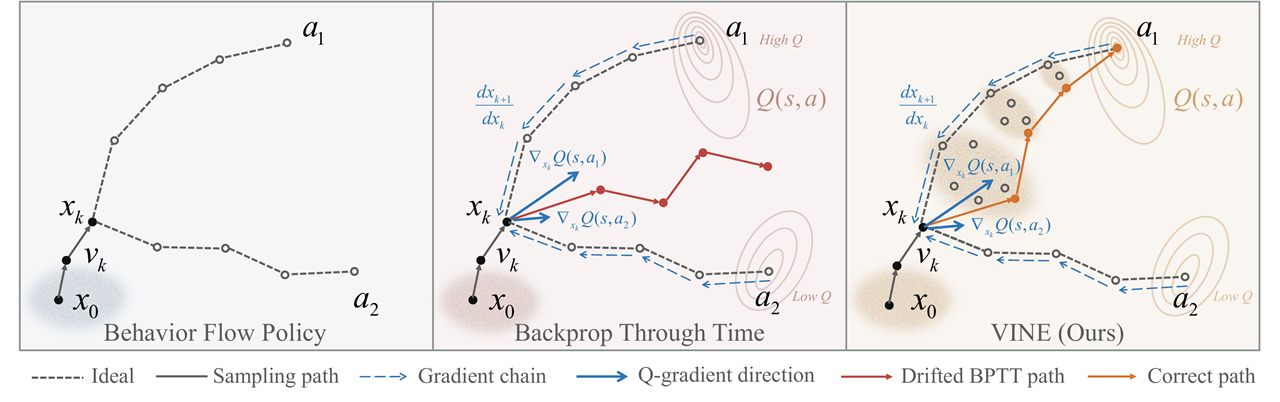
Rebuilds the interpolation state at each denoising step, so a flow-matching policy can take value gradients without the training blowing up.
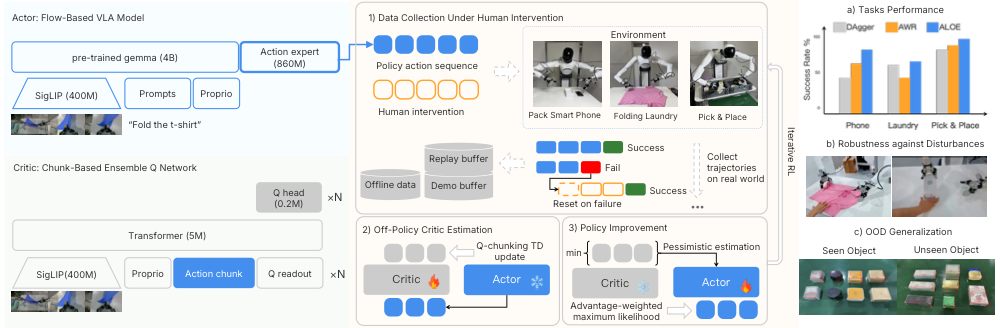
Scores the current policy on action chunks, then uses that to post-train a VLA on real robots.
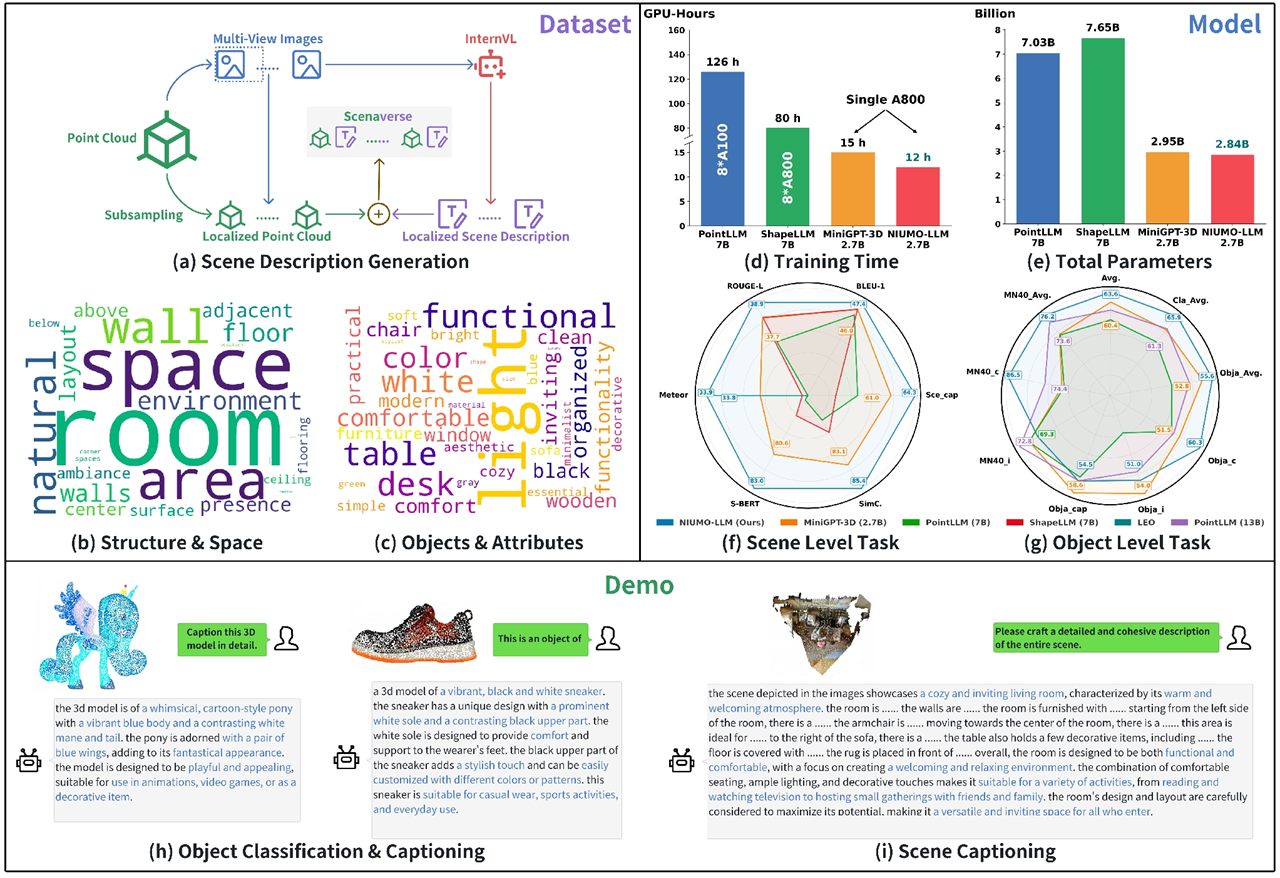
A large-scale scene description dataset together with a lightweight 3D-LLM.
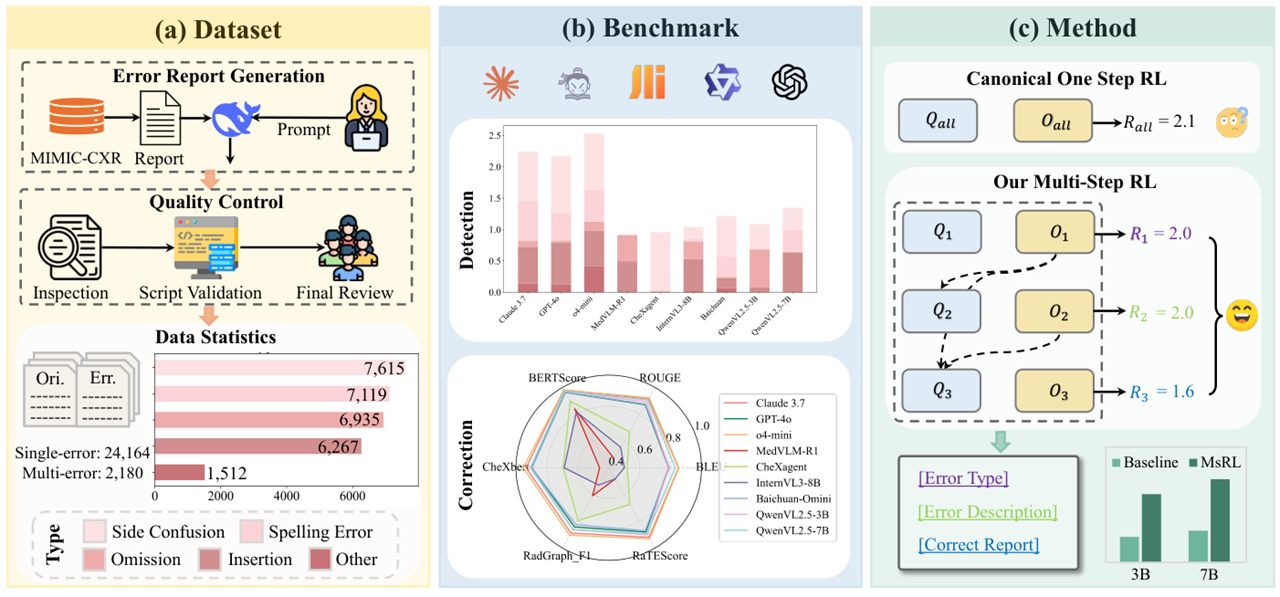
26,326 chest X-ray reports with injected errors, for testing whether a model can find the error and write the correction.
Given 3D point clouds and posed multi-view RGB-D images, RE0 combines 3D geometry, projection relationships and CLIP semantic features for 3D zero-shot instance segmentation.
Semantic features from a 2D foundation model reshape material property optimization for 3D Gaussian splatting.
Combining local and global structural features for few-shot point cloud semantic segmentation.
A greedy agent for meta-learning from learning curves, ranked 2nd in the MetaLC challenge.
An anatomical structure-guided framework that improves cross-modal alignment in medical vision-language pre-training.
A 60-card deck and a decision agent for the Pokémon Trading Card Game AI Battle. Team 宝糕手 (Poké Messters): 108th of 6,807, score 1011.9, Silver Medal.
Fine-tuning large language models on private datasets. Score 0.905, top 3% worldwide, Silver Medal.
Scale your device and escape from this geometry storm. 1st in innovation and 2nd in theme interpretation.